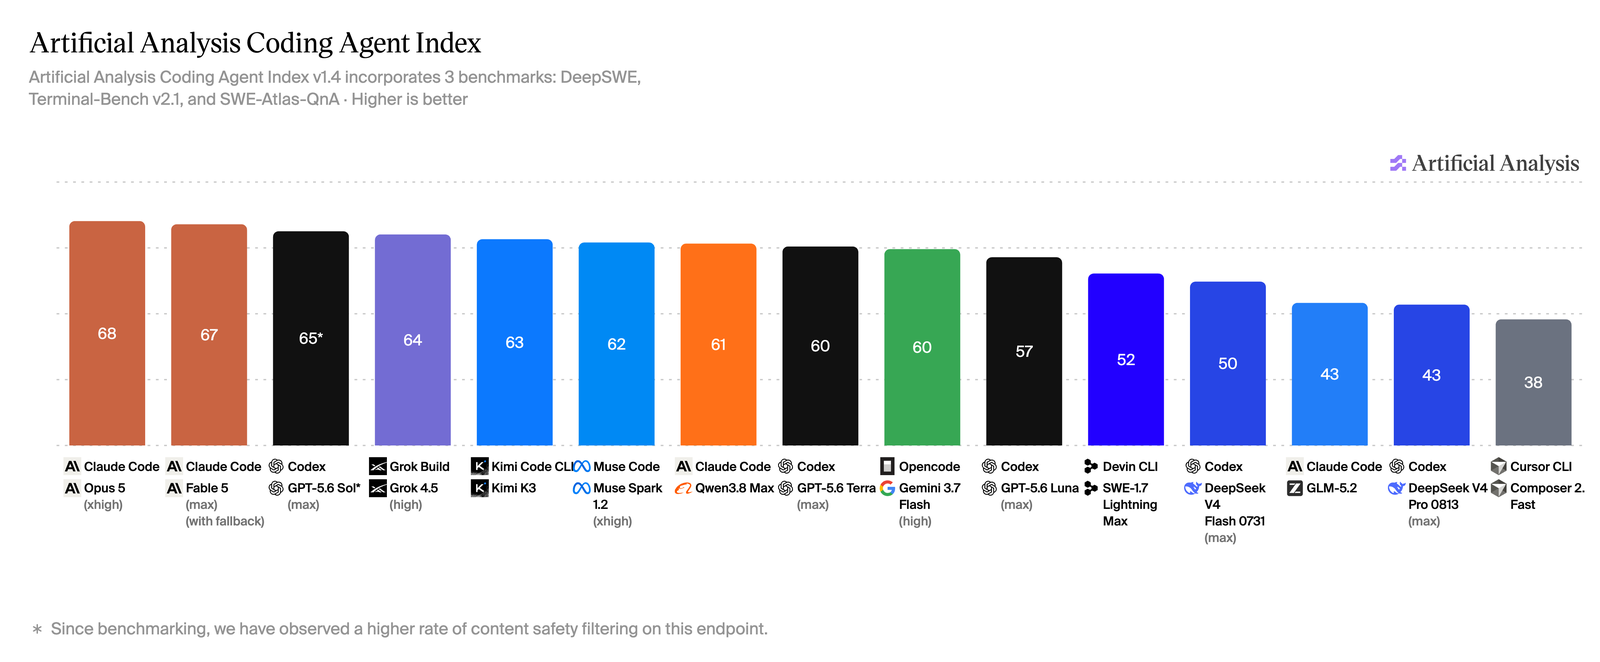
Three picks chosen from public coding benchmarks and current list prices: a top model for hard refactors, a value workhorse for daily shipping, and a budget option for high-volume jobs.
The strongest coding model on the LMRank leaderboard, with a 1M-token context window. It is also the most expensive of the three picks, so save it for work where getting it right first time beats token cost.
Use it if:
You want the strongest coding model available and bill by usage: large refactors, multi-step agent work, or million-token codebases where getting it right the first time matters more than token cost.
Skip it if:
You are running very high volumes on a budget. Frontier pricing adds up, and the cheaper picks below are close for everyday tasks.
From OpenAI’s GPT-5.6 family, with a 1M-token context window at a small fraction of the top pick’s per-token price.
Use it if:
You ship code all day and want frontier-family quality at a fraction of flagship pricing: a daily driver for IDE assistants, CI review bots, and high-volume generation.
Skip it if:
You need the absolute strongest reasoning on gnarly refactors; step up to the top pick for those.
Get one email when our coding picks change. No noise, no news treadmill.
How we chose
We start from the LMRank leaderboard (public benchmarks including SWE-bench, current pricing, and context windows), then narrow to models that make sense as an actual purchase decision. Every pick has a job: the top pick wins on capability, the value pick wins on capability per dollar, and the budget pick wins when cost is the constraint. Rankings and prices refresh continuously from public data sources; the verdicts here are editorial and re-checked whenever a pick changes.